如果你在电影行业工作或与之相关,那么这个月你很有可能已经用到了 The Numbers 的成果,无论你是否意识到这一点。
其手工调研的数据质量最高,追踪了超过 78,000 部电影和 236,000 名从业者的票房收入、预算、家庭影音和流媒体数据。它每年吸引超过 八百万访客,并被记者、学者、电影制作人、预测市场,甚至吉尼斯世界纪录视为权威定论。
而正是这种 GOAT 级别的地位,引发了今年三月的灾难性事件。
2026 年 3 月 5 日,TheNumbers.com 网站消失了。
该网站宕机超过一周,没有任何解释。一周后,它重新上线,但规模仅为原来的一小部分。历史图表、单部电影页面,甚至备受喜爱的 Report Builder 都不见了。
由于只有一句笼统的“我们正在重建,请耐心等待”的提示可供参考,互联网一如既往地做出了反应——困惑、愤怒和阴谋论。
Reddit 上甚至有一种理论认为,这是一次蓄意的rug pull,旨在削弱免费网站,从而将用户推向付费产品。
三个月后,我与 The Numbers 的创始人兼 CEO Bruce Nash 进行了长谈,了解事情的经过。他描述了一段相当不愉快且波折不断的经历:
我们收到了大量愤怒的邮件,人们说:‘你们以前有的那个页面现在怎么没了?’
在他的讲述中,有若干事情值得任何运营互联网、依赖互联网,或仅仅是欣赏互联网的人警惕。
首先,一些背景
1997 年 10 月 17 日星期五,数学家、前 IBM 软件开发者 Bruce Nash 上线了一个 Geocities 网站,追踪 300 部电影。
Bruce 在一篇20 周年纪念文章中描述了这次上线(由于后文将会明了的原因,这篇文章如今仅存于 Internet Archive):
我在一个 Access 数据库里点了一下按钮,把一些 HTML 页面上传到 Geocities,然后在 Hollywood Stock Exchange 的留言板上发了一条简短公告,告诉大家我开始分析电影票房,以帮助他们挑选可在 HSX 上交易的 MovieStocks。
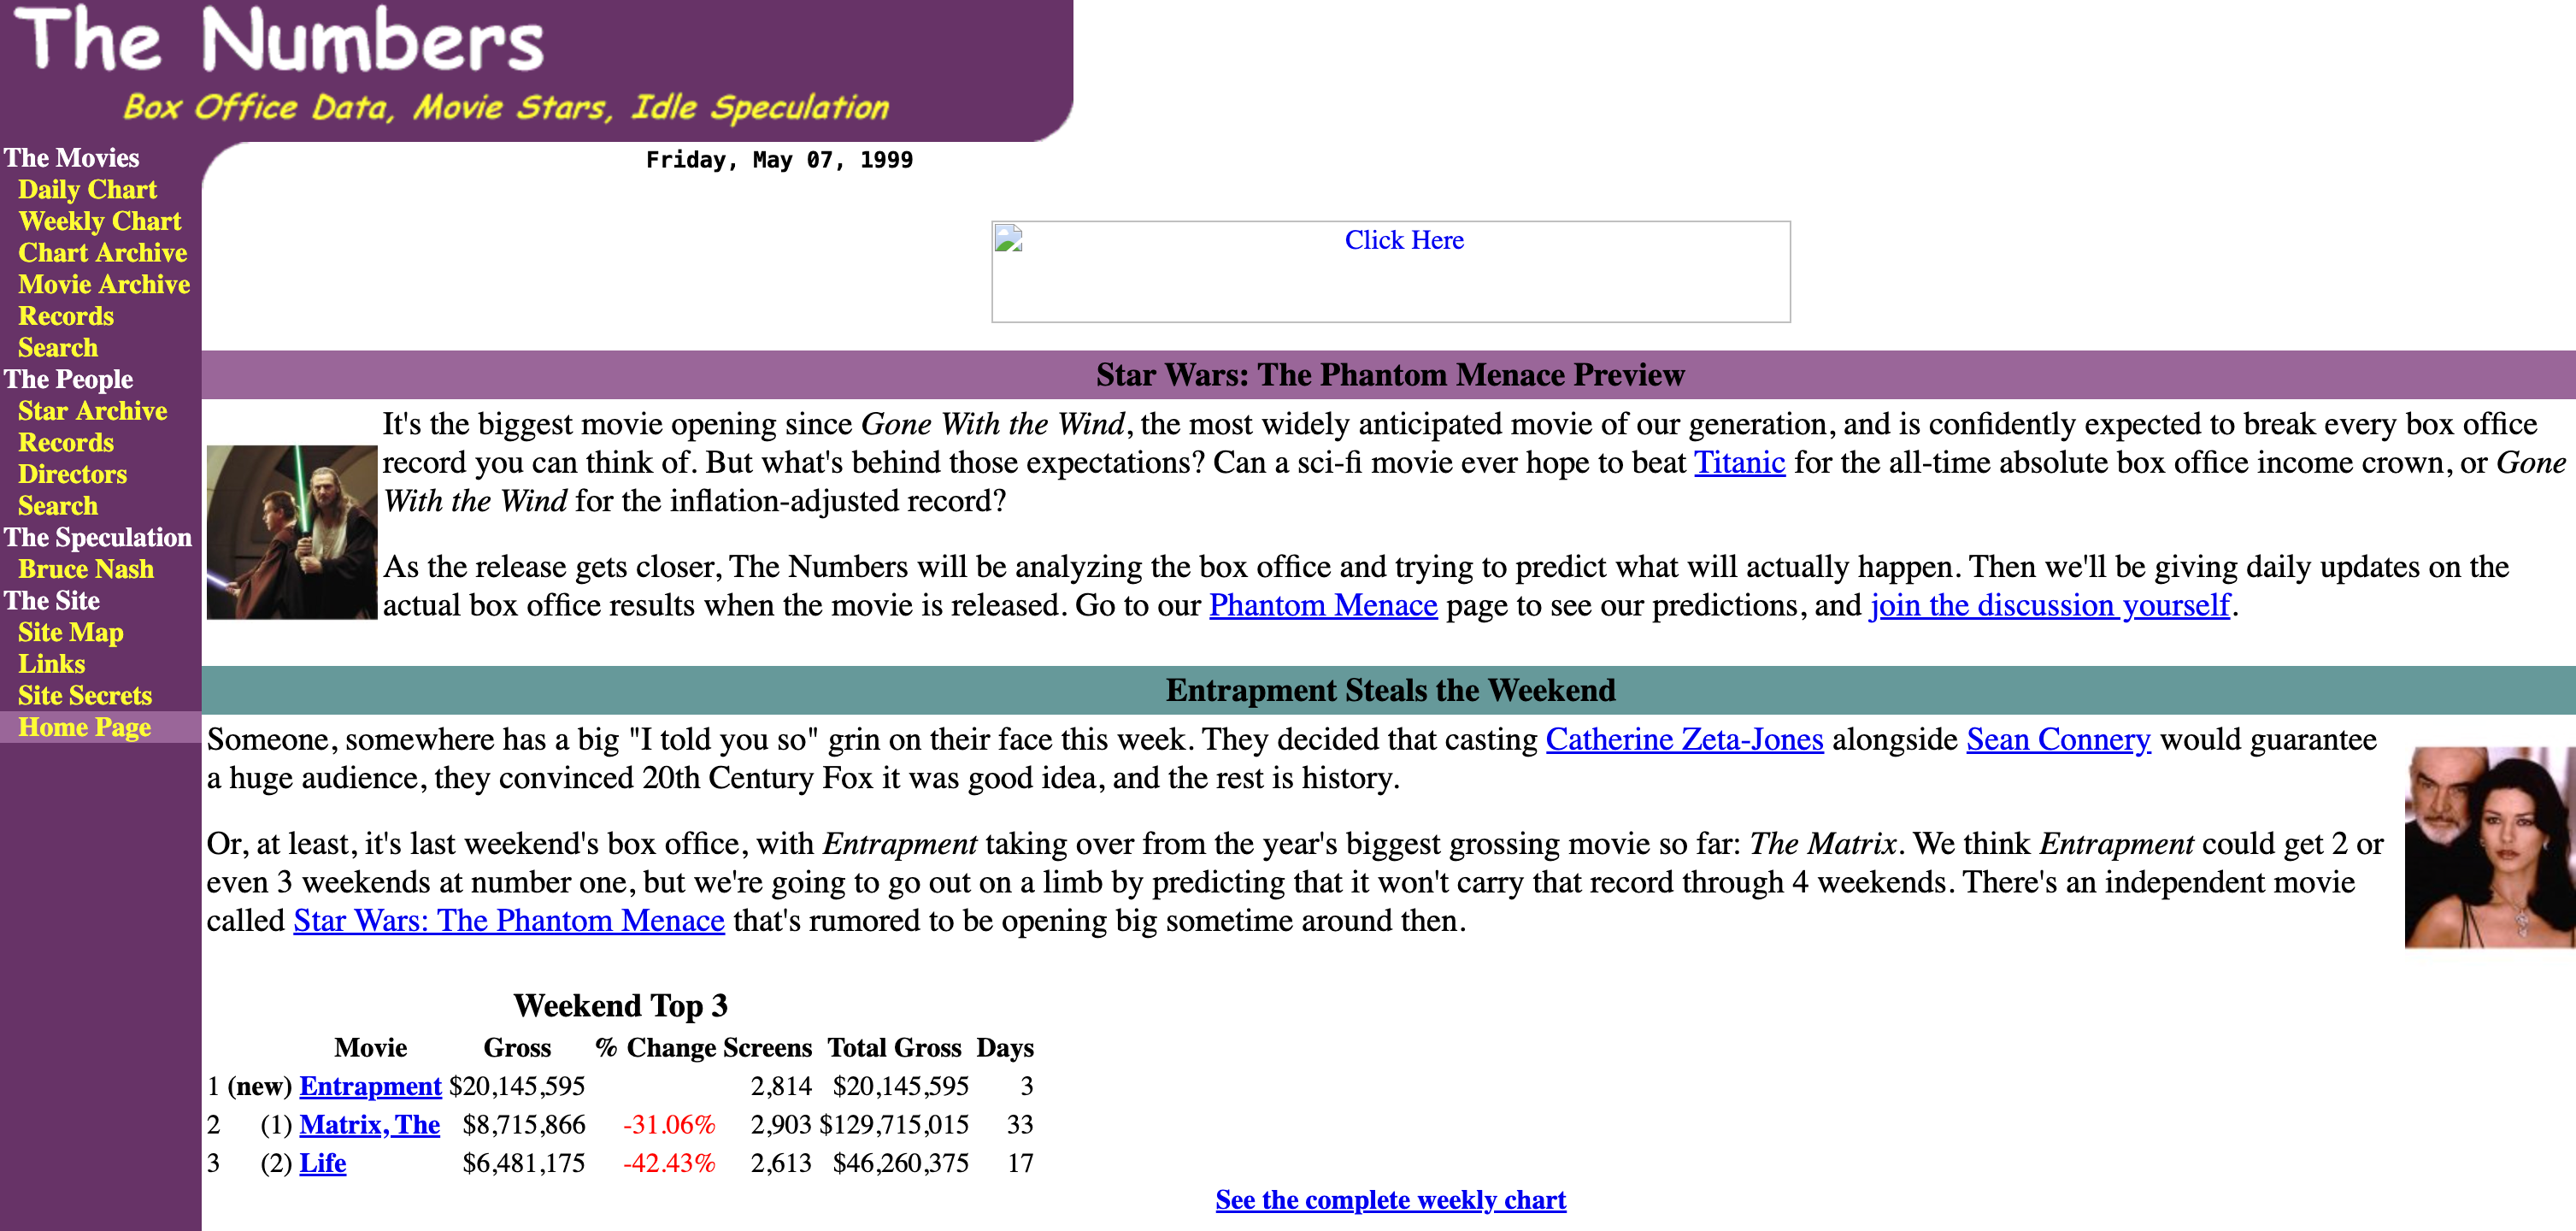
从这些不起眼的起点出发,Bruce 和他围绕该网站组建的团队将 The Numbers 打造成了电影行业最可靠的财务数据来源。
截至 2026 年初,该数据库追踪了 78,396 部电影、178,375 条院线发行记录和 236,176 名人物。
机器人来了
在 The Numbers 的存续期间,它所面临的挑战发生了翻天覆地的变化。在其最初的约二十五年里,流量尚在可控范围内,且大多彬彬有礼。正如 Bruce 所说:
在 AI 出现之前,我们面对的是人类流量,大多是行为规矩的搜索引擎爬虫,以及少数为了个人项目而抓取网站的人。如果有人过于贪婪,我们可以发现并封禁他们。
在过去几年里,全世界的网站所有者都目睹了自身网站流量的变化。最初只是人类在浏览,后来逐渐让位于数量不断增长的机器人。到 2024 年,自动化流量已经超过了人类流量,而就在上个月,Cloudflare 宣布机器人已占到网页请求的 57.5%。
The Numbers 分两波感受到了这一转变。第一波大约始于 2024 年:
随着 AI 训练加入搜索引擎爬虫的行列,我们看到爬取量大幅增加。AI 爬虫通常不如搜索引擎那样守规矩,这增加了我们保持网站平稳运行的管理负担。
而第二波更为猛烈,破坏性也更大:
大约在 2025 年 12 月,我们看到流量又一次大幅飙升,我将其归因于智能体 AI:一方面是响应提示词而抓取网站的 AI 智能体,另一方面是人们有能力编写抓取网站的智能体,两者叠加所致。
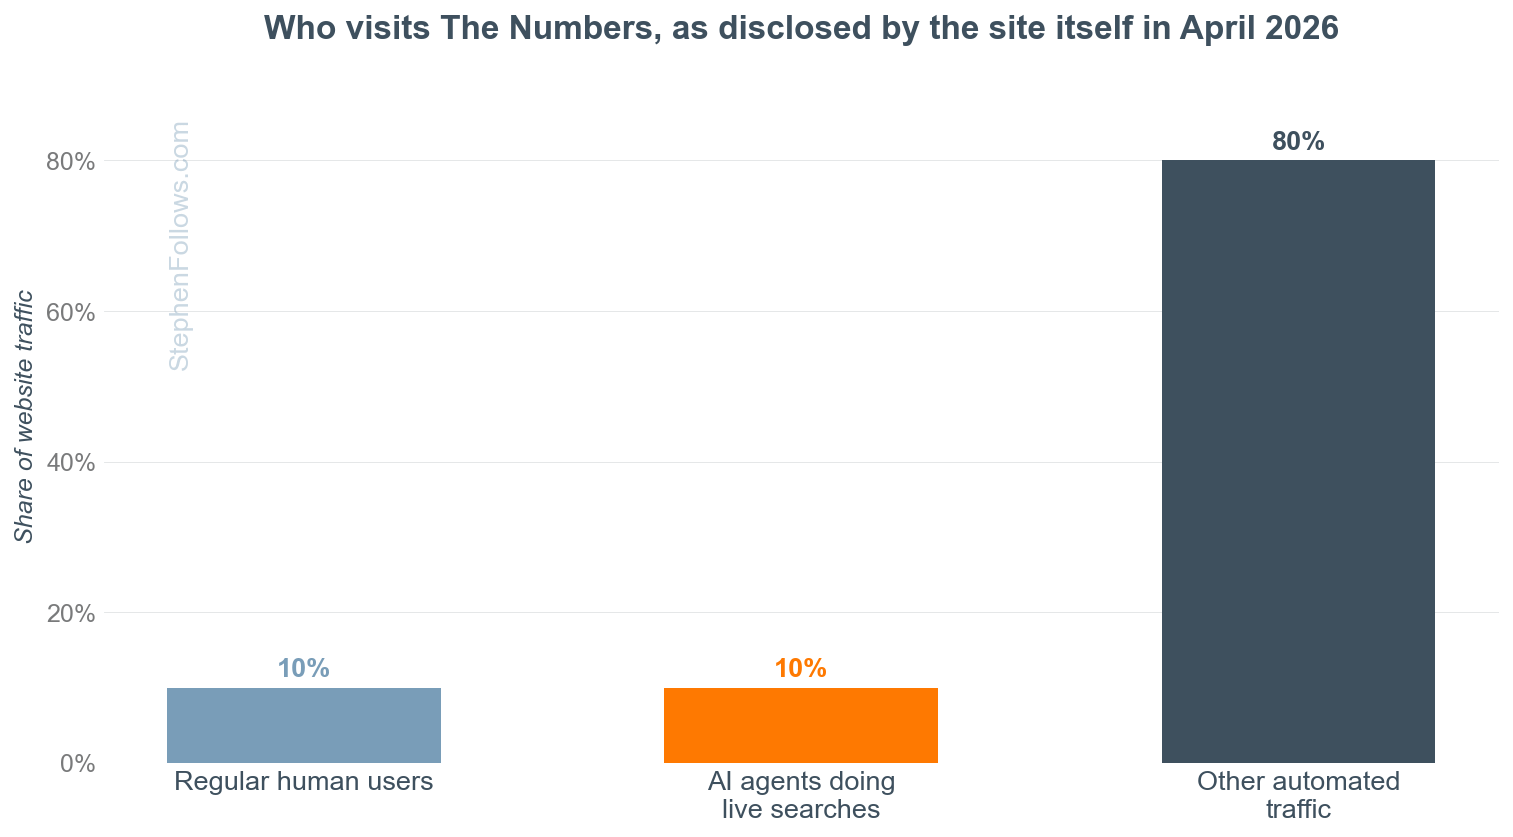
和所有数据丰富的网站一样,到 2026 年初,The Numbers 正被 AI 机器人以工业级规模反复抓取页面,遭受猛烈冲击。Bruce 表示,他们的流量中只有 10% 来自人类浏览网站,其余都来自 AI 机器人和自动化流量。
网站试图适应新的机器人
这给网站带来了巨大的压力,但 Bruce 和他的团队能够采取措施来缓解最糟糕的情况。其中最聪明的做法之一,是用机器人自己的语言与它们对话:
网站上有些内容是专门设计给 LLM 阅读的,这样它就能告诉对方“这里是你可以如何授权使用这些数据”,而不是“这里是你可以如何抓取这个网站”。这产生了巨大的效果。我们现在收到的授权咨询量大概是以往的十倍。
但缓解并不等于逃脱。从 12 月到 3 月初,团队一直在负载下艰难维持网站存活。Bruce 估计:
我们大约 90% 的时间都花在维持现有网站的运行上,而空闲时间则用来开发一个全新的改进系统。
网站的老旧让问题更加严重:它已有三十年历史,约 160,000 个源文件支撑着大约 200 万个页面。
然后,在 3 月 5 日星期四凌晨,服务器崩溃了。
团队紧急行动起来,试图弄清发生了什么,起初他们以为这只是 AI 流量规模过大所致。看来 AI 确实是罪魁祸首……但可能并不只是他们最初以为的那种方式。
在汹涌的智能体流量之下,网站日志显示出的东西比单纯的抓取更有针对性。正如 Bruce 所描述的:
其中一些使用合法 URL 访问该网站,另一些则在寻找后门,最可能的目的是在数据出现在网站上之前就获取它们,或者操纵呈现给用户的数据。
在一位从事网络安全工作的朋友的建议下,旧服务器一直保持关闭。永久关闭。恢复备份并让这个已有三十年历史的网站重新上线,意味着要保护 160,000 个遗留文件,抵御那些已经花了数月时间探测它们的攻击者。
团队在新基础设施上匆忙搭建了一个网站的精简版本,至少可以在他们评估发生了什么以及下一步该怎么做期间,继续提供最新的票房数据。该版本于 3 月 13 日星期五上线。
谁会想要一个票房网站的私人访问权限呢?
乍一看,The Numbers 似乎并不是一个显而易见的目标。它不收集信用卡信息,也没有可以在暗网上倒卖的诱人客户数据。它只是一家小型独立公司,发布电影的票房收入。
一个人怎么能指望仅凭对其网站的私人访问权限就赚到钱呢?
如果你还没猜到的话,它与预测市场有关。
Polymarket每周都会针对首映周末开设市场,并将 The Numbers 指定为最终的真相来源:
一旦 3 天首映周末的数值最终确定,该影片 The Numbers 页面“Box Office”标签下的“Daily Box Office Performance”数据将用于结算该市场。
按金融市场的标准衡量,任何单个周末市场的金额都不算大,通常在数万到数十万美元之间,而任意时刻所有活跃票房市场的总额约为几百万美元。
如果你能每周都比其他人更早看到 The Numbers 的数据,你就会比所有其他交易者拥有显著优势——在数据发布前稍早获知答案,就能让你抢跑交易。
在这种情况下,很难确定究竟发生了什么。我们知道日志显示该网站被自动化探测和抓取持续了数月,但最终是什么导致网站宕机,以及是谁所为,仍然是一个未解之谜。
但有人利用 AI 在预测市场中获取优势这一理论完全可信。The Numbers 的经历告诉我们:
我们现在所处的世界里,一个电影统计网站也值得被黑客攻击,因为预测市场让任何人都能把几乎任何数据变成金钱。
如今,只要订阅一个便宜的 AI 服务,任何人都能入侵网站。
面对大规模智能体 AI 机器人集群的冲击,我们现有的网络脆弱得令人难以置信。
话说回来,如今搞黑客攻击到底有多难?
2025 年 11 月,Anthropic(Claude 背后的 AI 实验室)发布了一份报告,称其为首个有记录的由 AI 编排的网络间谍活动。一个受国家资助的组织利用其编程工具攻击了大约 30 个机构,其中 AI 承担了 80% 到 90% 的工作,人类仅在每次行动中的 4 到 6 个决策点上介入。
Anthropic 自己的结论是:
实施复杂网络攻击的门槛已大幅降低,我们预测这一门槛还将继续下降。
在一份更早的威胁报告中,Anthropic 说得更加直白:
几乎没有技术技能的犯罪分子正在利用 AI 实施复杂操作,比如开发勒索软件,而这在过去需要多年的训练才能做到。
与此同时,一个名为 XBOW 的自主 AI 渗透测试工具 登上了 HackerOne 美国排行榜榜首,该榜单排名的是那些为获取赏金而在真实公司中寻找安全漏洞的人(此前全部是人类),它一路提交了近 1,060 个漏洞。
获取一个拥有 160,000 个遗留文件的三十年老网站的访问权限,正是 AI 工具已使其探测成本极低的那种已知漏洞面。曾经保护小型网站免受除最坚定攻击者之外所有人入侵的专业知识壁垒,如今已基本消失。
The Numbers 现在该怎么办?
Bruce 和他的团队相对幸运。尽管整个网站在一夜之间被瘫痪,他们仍能继续运营。The Numbers 一直免费使用,而且过去几年该网站并未严重依赖广告,因此这次宕机并未摧毁他们所依赖的收入来源。
他们的核心业务与通过 OpusData 服务销售批量数据、为电影制作人和投资者生成对比分析报告,以及出版 Business Report 相关——所有这些都未受公开网站宕机的影响。
但他们确实需要从零开始构建一个全新的网站,来承载那 78,396 部电影、178,375 条发行记录和 236,176 位人物。从备份恢复网站不是一个选项,正如 Bruce 所指出的:
很明显,我们不能再把那个服务器重新上线,因为它不可避免地会再次被打垮,可能几分钟之内就会发生。
这就是为什么该网站在三月中旬以最精简的形态回归,也是为什么各项功能是逐步恢复而非一次性全部上线。
眼下,团队不得不重新思考:在 2026 年,一个公开网站到底意味着什么。Bruce 的分析是,The Numbers 过去服务两类受众(人类和搜索引擎),而现在大约服务六类:人类、搜索引擎、LLM 训练任务、基于提示词的 AI 流量、智能体 AI,以及预测市场的下注者。每一类都有不同的需求和不同的流量特征。正如他所说:
我们已经从一个运营网站只需关注三件事(内容、广告和 SEO)的世界,变成了每个设计决策都要考虑大约八到十个不同因素的局面。
他说,目标是服务所有六类受众,通过新的 OpusData 服务和面向 Business Report 订阅者的在线功能来实现,而且重要的是,帮助网站的普通人类用户重新获得它一直以来提供的数据,其中一部分将以新的、改进后的形式呈现。
机器人抓取到底能有多严重?
说实话,相当严重。严重到像 Bruce 这样的网站所有者不得不质疑:一个需要花费如此多时间和金钱来构建和防御的东西,到底还有多大价值。
Cloudflare保护着全球很大一部分网站,它公布的数据显示了每个 AI 平台在抓取多少页面后,才会向被它抓取的网站回送一位访客。
Google 每向你回送一位访客,大约会抓取五个页面。OpenAI 抓取超过 1,000 个。Anthropic 每引荐一位访客,抓取的页面超过 38,000 个。
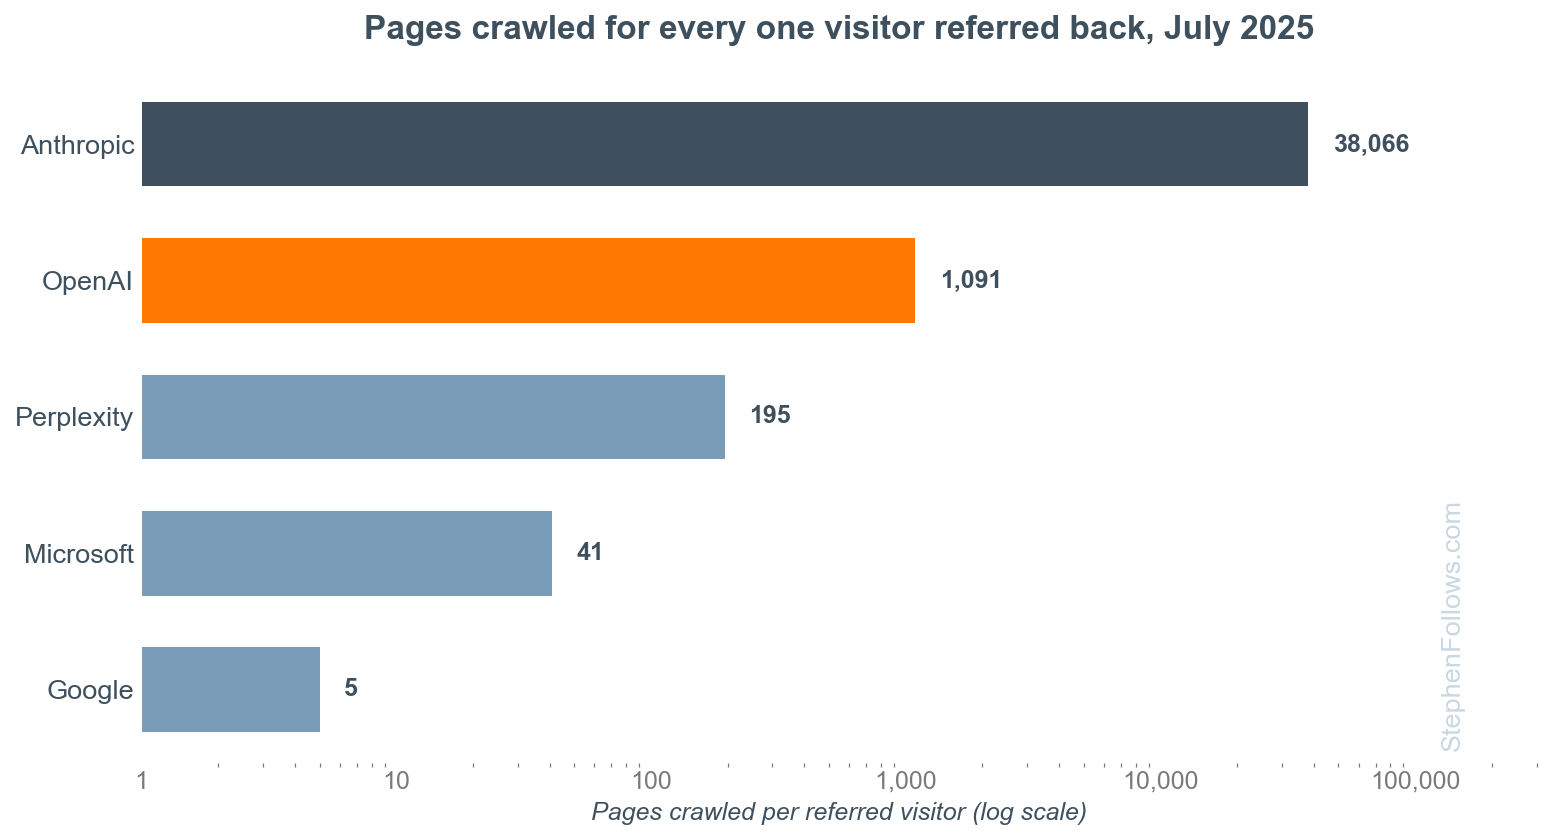
请注意,这个刻度是对数的,也就是说底部每前进一格,都比上一格大十倍,因为否则这些差异之大,简直让我无法把它们放进同一张图表里。
在互联网迄今为止的历史中,开放网络的原则是:作为让搜索引擎机器人读取你网站的回报,它们会给你送来读者。但现在,这笔交易不再成立了。机器人的数量已经爆炸式增长,而它们不再回送任何人。
当这股洪流对准一个小网站时,它可能推高带宽账单,甚至可能让整个网站宕机。能够与 Bruce 的经历产生共鸣的网站包括:
Read the Docs,一家为开源软件托管文档的非营利组织,它目睹单个爬虫在一个月内下载了 73 TB 的压缩 HTML,使其带宽费用超过 $5,000。
iFixit,这个维修指南数据库,在一天之内记录到来自 Anthropic 爬虫的一百万次访问。
Triplegangers是一家销售 3D 扫描数据的七人公司,它在营业时间被 OpenAI 的爬虫机器人打到下线,其 CEO 将此描述为“基本上就是一次 DDoS 攻击”。代码托管服务 SourceHut 的创始人报告称,他“在任何一周里都要花 20-100% 的时间”来对抗 AI 爬虫,“每周都会发生数十次短暂宕机”。
Linux 新闻网站 LWN 的编辑描述了来自“数以百万计的 IP 地址”的爬虫流量,并得出结论:“这确实是一次分布式拒绝服务攻击”。
当 GNOME 开源项目测量其流量时,大约 97% 竟然是机器人。
一所大学图书馆在 48 小时内封禁了 16,000 个 IP 地址,以保持其目录在线。
运营 Wikipedia 的 Wikimedia Foundation 在2025 年 4 月报告称,机器人约占其页面浏览量的 35%,但至少占其最昂贵流量的 65%,因为爬虫会大量读取人类读者很少触及的冷门页面。
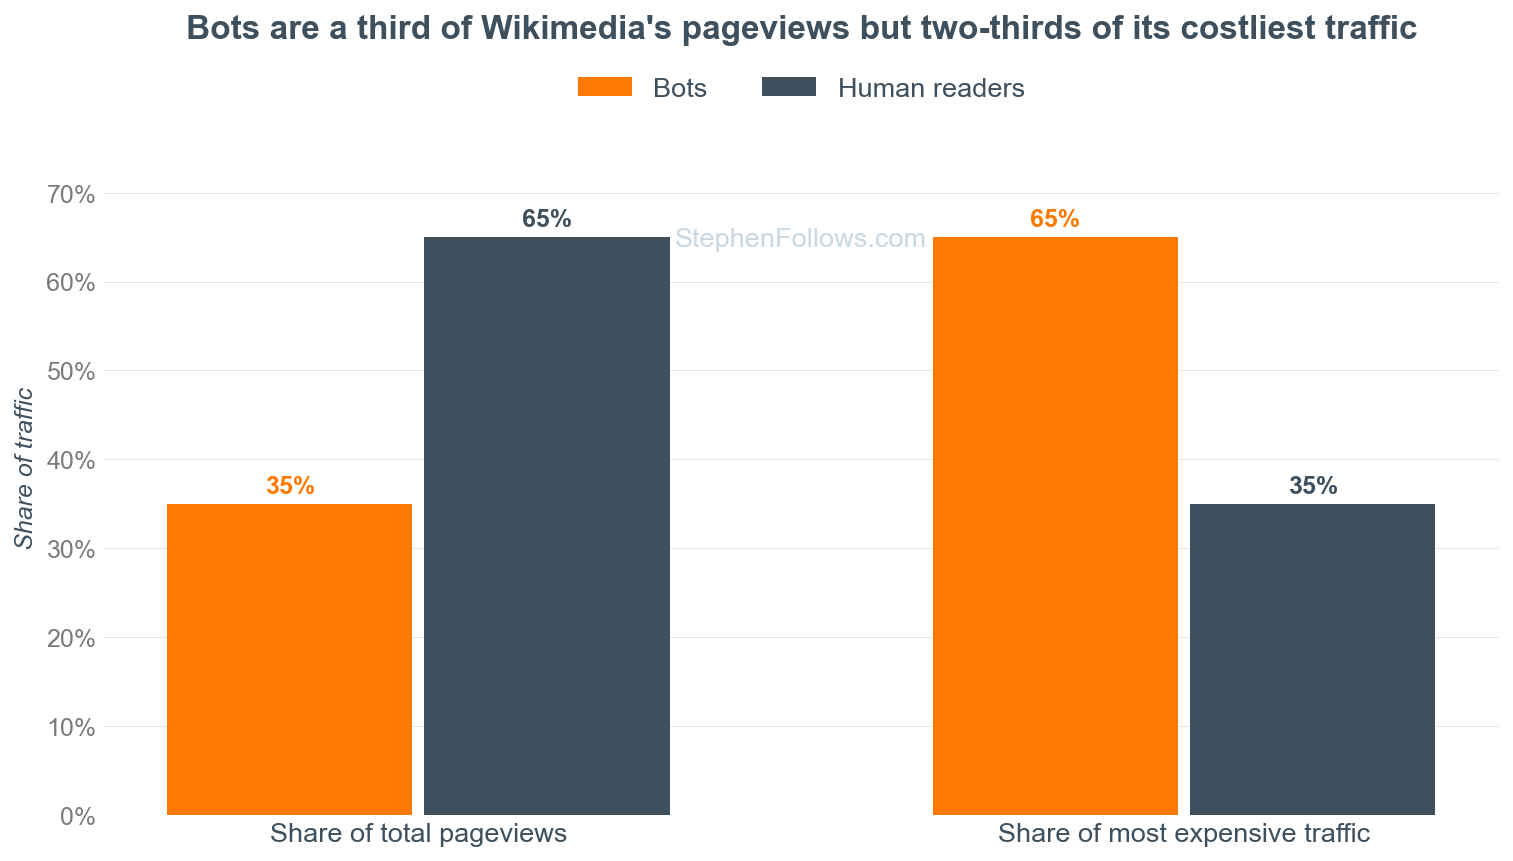
六个月后,挤压的另一半也来了:Wikipedia 的人类页面浏览量同比下降约 8%,因为人们越来越多地从 AI 摘要中获取 Wikipedia 的知识,却从不访问 Wikipedia。机器正在以工业级规模同时夺走内容和读者。
在公开环境中测试
AI 工具是人类有史以来创造过的最强大、也最具破坏性的事物之一。而它们正在现实世界中,被公众实时地进行着有效的测试。当年曼哈顿计划试图弄清其原子技术的威力时,可没有每天早上把设计图纸发给所有人,然后看看哪些房子被炸毁。
我们迄今所构建的这个世界,对于我们所有人如今都能接触到的 AI 模型所具有的威力和规模,准备得极其不足。
我并不希望这听起来像是一场片面的反 AI 恐慌宣传。AI 以及它能为人类带来的东西,有很多值得称道之处。但我们确实需要认真思考我们当下正迈入的这个新世界。
最先崩溃的,是为旧互联网而建的那些东西。开放网络建立在这样一些假设之上:访问者大多是真人,流量大致能反映读者规模,以及为你的网站提供服务的成本与你从中获得的价值相关。这些假设如今每一条都已过时。
一年前,Cloudflare 推出了 按爬取付费,让网站可以按页面向 AI 爬虫收费。上周,它更进一步,宣布了一种按使用付费的模式:当出版方的内容真正出现在 AI 回答中时,出版方就能获得报酬;同时它宣布,从 9 月 15 日起,其客户那些靠广告支撑的页面将默认屏蔽未付费的“混合用途”爬虫。
这一切是否奏效,取决于 AI 公司是选择配合,还是绕开它。但正如 Bruce 对我所说,总得有人去尝试。
尾声
让我们暂时把具体细节放到一边,想想这里究竟发生了什么。
一个受人喜爱、实用、免费的网站,由一位能干而诚实的人精心运营了近三十年,却被新 AI 经济的两个特征夹击碾碎。
不可持续的机器流量从上方对其狂轰滥炸,而一个很可能是出于经济动机的入侵者——在一个入侵网站从未如此容易的世界里行事——最终将其击垮。
Bruce 的生意和生计之所以得以幸存,仅仅是因为这个网站并非他生意的全部。
其他人就没有这么幸运了。就在上周,一家经营了 37 年的德国纺织公司 ZEGO,在 3 月遭遇一次网络攻击、导致其生产停摆六周之后,申请了破产。与 The Numbers 不同,他们没有其他业务可以依靠。
网络上充斥着独立档案库、爱好者数据库、本地新闻网站、论坛、参考资料。数十年积累的人类心血,运行在老旧代码之上,由小团队或单个人维护,默默支撑着我们共享知识中远超任何人所承认的份额。
《The Numbers》要回归了,而且比以往做得更好。我鼓励大家继续使用它、继续支持它;如果你是众多曾愤怒地给 Bruce 发邮件追问某个页面为何消失的人之一,既然现在知道了原因,或许可以再发一封语气更友善的邮件。
If you work in or around the film industry, there is a decent chance you have used the work of The Numbers this month, whether you realise it or not.
Its hand-researched data is the highest quality, tracking box office grosses, budgets, home video and streaming across more than 78,000 films and 236,000 people. It gets north of eight million visitors a year, and is treated as THE definitive authority by journalists, academics, filmmakers, prediction markets, and even Guinness World Records.
And it was this GOAT status which caused the catastrophic events of March this year.
On the 5th March 2026, TheNumbers.com website vanished.
The site was down for over a week, without explanation. A week later, it resurfaced at a fraction of its former size. Gone were the historical charts, the individual movie pages, and even the much-loved Report Builder.
With only a generic “we’re rebuilding, please bear with us” message to go on, the internet responded as it always does - with confusion, anger, and conspiracy theories.
One Reddit theory even suggested it was a deliberate rug pull designed to cripple the free site to push people towards paid products.
Three months on, I spoke at length with Bruce Nash, founder and CEO of The Numbers, about what happened. He describes quite an unpleasant and eventful experience:
We got a lot of angry emails from people who are like, 'Where's this page that you used to have and you don't have anymore?'
Within his tale are a number of things that should worry anyone who runs, relies on, or simply appreciates the internet.
First, some background
On Friday 17 October 1997, mathematician and former IBM software developer Bruce Nash launched a Geocities site that tracked 300 films.
Bruce described the launch in a 20th anniversary essay (which now survives only in the Internet Archive, for reasons that will become clear):
I hit a button in an Access database, uploaded some HTML pages to Geocities, and made a brief announcement on the Hollywood Stock Exchange message boards to let people know that I was starting to analyze box office for films to help them pick MovieStocks to trade on HSX.
From those humble beginnings, Bruce and the team he built around the site turned The Numbers into the film industry's most reliable financial source.
At the start of 2026, the database tracked 78,396 movies, 178,375 theatrical release records, and 236,176 people.
The robots arrive
During its lifetime, the challenges The Numbers has faced have changed immensely. For its first quarter century or so, the traffic was manageable and mostly polite. As Bruce puts it:
Pre-AI, we got human traffic, mostly well-behaved search engine crawlers, and a few people crawling the site for personal projects. If someone got too greedy, we could spot them and block them.
Over the past couple of years, website owners the world over have seen their web traffic change. What was initially only people browsing gave way to an ever-increasing number of bots. By 2024, automated traffic had surpassed human traffic, and just last month, Cloudflare announced that bots had reached 57.5% of web page requests.
The Numbers felt this shift in two distinct waves. The first started around 2024:
We saw a big increase in crawls as AI training joined the search engine crawlers. The AI crawlers are generally less well-behaved than the search engines, which increased the management tasks for us to keep the site running smoothly.
And the second wave was stronger and more damaging:
Around December 2025, we saw another big spike in traffic which I attribute to agentic AI: a combination of AI agents that scrape sites in response to prompts, and people being able to write agents that scrape sites.
Like every data-rich site, by early 2026 The Numbers was being hammered hard by AI bots scraping its pages over and over at an industrial scale. Bruce says that only 10% of their traffic is from humans browsing the site, with the rest coming from AI bots and automated traffic.
Websites try to adapt to the new robots
This put enormous strain on the site, but Bruce and his team were able to take measures to mitigate the worst of it. One of the cleverest was talking to the robots in their own language:
There’s stuff on the site which is designed for an LLM to read, so that it can tell somebody ‘here’s how you licence the data’ rather than ‘here’s how you scrape the website’. It’s had a huge effect. We’re now getting probably ten times the volume of licensing enquiries.
But mitigation is not the same as escape. From December through early March, the team struggled to keep the site alive under the load. Bruce estimates that:
Around 90% of our time was spent keeping the existing site running while we spent our spare moments working on a new and improved system.
The problem was compounded by the site’s age: thirty years old, with approximately 160,000 source files serving around 2 million pages.
Then, in the early hours of Thursday 5 March, the servers collapsed.
The team scrambled to understand what had happened, initially assuming it was the sheer weight of AI traffic. It seems AI was to blame... but possibly not only in the way they first thought.
Buried in the flood of agentic traffic, the site’s logs showed something more pointed than scraping. As Bruce describes it:
Some of these used the site using legitimate URLs, others were looking for back doors, most likely so they could get to the data before it appeared on the site, or to manipulate the data presented to users.
On the advice of a friend who works in cybersecurity, the old server stayed off. For good. Restoring the backups and nursing the thirty-year-old site back online would have meant defending 160,000 legacy files against attackers who had spent months probing them.
The team rushed up a skeleton version of the website on new infrastructure, which could at least keep delivering the latest box office figures while they took stock of what had happened and what to do next. It went live on Friday 13 March.
Who would want private access to a box office website?
At first glance, The Numbers may not seem like an obvious target. It doesn’t collect credit card information, and there is no juicy customer data to flip on the dark web. It is a small, independent company that publishes how much money movies make.
How could someone expect to make money purely from having private access to their site?
In case you haven’t guessed it yet, it’s linked to prediction markets.
Polymarket runs weekly markets on opening weekends, and names The Numbers as the ultimate source of truth:
The ‘Daily Box Office Performance’ figures found on the ‘Box Office’ tab on this movie’s The Numbers page will be used to resolve this market once the values for the 3-day opening weekend are final.
The sums on any single weekend market are modest by financial-market standards, typically in the tens to hundreds of thousands of dollars, with a couple of million dollars across live box office markets at any given time.
If you could see The Numbers data before everyone else, every single week, you would have a significant edge over all the other traders - learning the answers slightly ahead of publication would allow you to front-run the trades.
In a situation like this, it is hard to know for certain what happened. We know that the logs showed months of automated probing and scraping of the site, but what finally brought the site down, and who did it, remains an open question.
But the theory that someone used AI to develop an advantage in a prediction market is entirely plausible. The Numbers experience shows us that:
We now live in a world where a movie statistics website is worth hacking because prediction markets empower anyone to turn almost any data into money.
Hacking websites is now something anyone can do with a cheap AI subscription.
The web, as we have it, is incredibly fragile in the face of large-scale swarms of agentic AI bots.
How hard is hacking these days, anyway?
In November 2025, Anthropic (the AI lab behind Claude) published a report on what it called the first documented AI-orchestrated cyber espionage campaign. A state-sponsored group had used its coding tool to attack roughly 30 organisations, with the AI performing 80% to 90% of the work and humans stepping in at only 4 to 6 decision points per campaign.
Anthropic’s own conclusion was:
The barriers to performing sophisticated cyberattacks have dropped substantially, and we predict that they’ll continue to do so.
In an earlier threat report, Anthropic were even clearer:
Criminals with few technical skills are using AI to conduct complex operations, such as developing ransomware, that would previously have required years of training.
Meanwhile, an autonomous AI penetration tester called XBOW reached number one on HackerOne’s US leaderboard, the ranking of the people (formerly all people) who find security holes in real companies for bounties, submitting nearly 1,060 vulnerabilities along the way.
Getting access to a thirty-year-old website with 160,000 legacy files is exactly the kind of known-flaw surface that AI tools have made cheap to probe. The expertise barrier that once protected small sites from all but the most determined attackers has largely evaporated.
What now for The Numbers?
Bruce and his team were relatively lucky. Despite having their entire site knocked out overnight, they were able to keep going. The Numbers has always been free to use, and the site hasn’t relied heavily on advertising for the past few years, so the outage didn’t destroy an income stream they depended on.
Their core business is tied to selling bulk data through the OpusData service, producing comp analysis reports for filmmakers and investors, and publishing the Business Report - all of which were unaffected by the public site going down.
But they do need to build an entirely new website, from scratch, to host those 78,396 movies, 178,375 release records and 236,176 people. Restoring the site from a backup wasn’t an option, as Bruce points out:
It was really clear that we couldn’t just put that server up again, because it would inevitably be brought down again, possibly within minutes.
That is why the site came back bare-bones in mid-March, and why features are returning gradually rather than all at once.
Right now, the team is having to reconsider what a public website even means in 2026. Bruce’s analysis is that The Numbers used to serve two audiences (human beings and search engines) and now serves roughly six: humans, search engines, LLM training runs, prompt-based AI traffic, agentic AI, and prediction market punters. Each has different needs and a different traffic profile. As he puts it:
We’ve gone from a world where running a web site meant focusing on three things (content, ads, and SEO) to about eight to ten different factors that go into every design decision.
The goal, he says, is to support all six audiences, with new OpusData services and online features for Business Report subscribers, and, importantly, to help regular human users of the site regain the data it has always provided, some of it in new and improved form.
How bad could bot scraping really be?
Pretty bad, tbh. Enough that site owners such as Bruce have to question the value of something that will take so much time and money to build and defend.
Cloudflare, which protects a huge share of the world’s websites, publishes data on how many pages each AI platform crawls for every one visitor it sends back to the websites it crawled.
Google crawls about five pages for every visitor it sends you. OpenAI crawls over 1,000. Anthropic crawls over 38,000 pages for every single visitor it refers.
Note that the scale is logarithmic, i.e. each step along the bottom is ten times bigger than the last, because otherwise the differences are quite literally too large for me to include on one chart.
For the history of the internet to date, the principle of the open web was that, in return for letting the search engine robots read your site, they would send you readers. But now, that trade no longer applies. The number of robots has exploded, and they no longer send anyone back.
When this firehose is aimed at a small site, it can inflate the bandwidth bill and possibly even take down an entire site. Sites which can relate to Bruce’s experience include:
Read the Docs, a non-profit that hosts documentation for open-source software, who watched a single crawler download 73 terabytes of zipped HTML in one month, costing it over $5,000 in bandwidth.
iFixit, the repair-guide database, logged a million hits from Anthropic’s crawler in a single day.
Triplegangers, a seven-person company selling 3D scans, was knocked offline during business hours by OpenAI’s bot, in what its CEO described as “basically a DDoS attack”. The founder of code-hosting service SourceHut reported spending “anywhere from 20-100% of my time in any given week” fighting AI crawlers, with “dozens of brief outages per week”.
The editor of Linux news site LWN described crawler traffic from “literally millions of IP addresses” and concluded: “it is a distributed denial-of-service attack”.
When the GNOME open-source project measured its traffic, roughly 97% turned out to be bots.
A university library banned 16,000 IP addresses in 48 hours to keep its catalogue online.
The Wikimedia Foundation, which runs Wikipedia, reported in April 2025 that bots account for about 35% of its pageviews but at least 65% of its most expensive traffic, because crawlers bulk-read obscure pages that human readers rarely touch.
Six months later came the other half of the squeeze, when Wikipedia’s human pageviews fell roughly 8% year on year, as people increasingly get Wikipedia’s knowledge from AI summaries without ever visiting Wikipedia. The machines are taking both the content and the readers at an industrial scale, too.
Testing it in public
AI tools are some of the most powerful and destructive things humans have ever created. And they are being effectively tested by the public in real time in the real world. When the Manhattan Project was trying to work out the power of their atomic tech, they did not do so by sending everyone the specs each morning and seeing which houses blew up.
The world we have built thus far is so incredibly ill-prepared for the power and scale of the AI models we all have access to.
I don’t wish for this to sound like a one-sided anti-AI fear campaign. There is a lot to like about AI and what it can do for the human race. But we do need to consider the world we’re currently stepping into.
What breaks first are the things built for the old internet. The open web was built on assumptions such as that visitors are mostly human, that traffic roughly tracks readership, and that the cost of serving your site is related to the value you get from serving it. Every one of those assumptions is now out of date.
A year ago, Cloudflare launched pay-per-crawl, letting sites charge AI crawlers per page. Last week, it went further, announcing a pay-per-use model in which publishers get paid when their content actually appears in an AI answer, and declaring that, from 15 September, its customers’ ad-supported pages will block unpaid “mixed-use” crawlers by default.
Whether any of this works depends on whether the AI companies play along rather than route around it. But as Bruce put it to me, somebody has to try.
Epilogue
Let’s look beyond the specifics for a moment and consider what happened here.
A beloved, useful, free website, run carefully by a competent, honest person for nearly thirty years, was crushed between two features of the new AI economy.
Unsustainable machine traffic hammered it from above, and in all likelihood a financially motivated intruder, operating in a world where breaking into websites has never been easier, took it down.
Bruce’s business and livelihood survived only because the website was not the whole business.
Others have not been so fortunate. Just last week, ZEGO, a German textile firm that had been in business for 37 years, filed for insolvency after a single cyberattack in March shut down its production for six weeks. Unlike The Numbers, they had no other business to fall back on.
The web is full of independent archives, hobby databases, local news sites, forums, reference works. Decades of accumulated human effort, running on old code, maintained by small teams or single individuals, quietly holding up far more of our shared knowledge than anyone acknowledges.
The Numbers is coming back, better built than before. I would encourage you to keep using it, keep supporting it, and, if you are one of the many people who emailed Bruce in fury about a missing page, perhaps send a kinder one now you know why it was missing.