OpenAI 刚刚报告称,他们的系统入侵了 HuggingFace。
很多人感到担忧。例如 Yoshua Bengio:
其中有一些重要的细微差别,但人们的担忧并非没有道理。以下是我的看法。
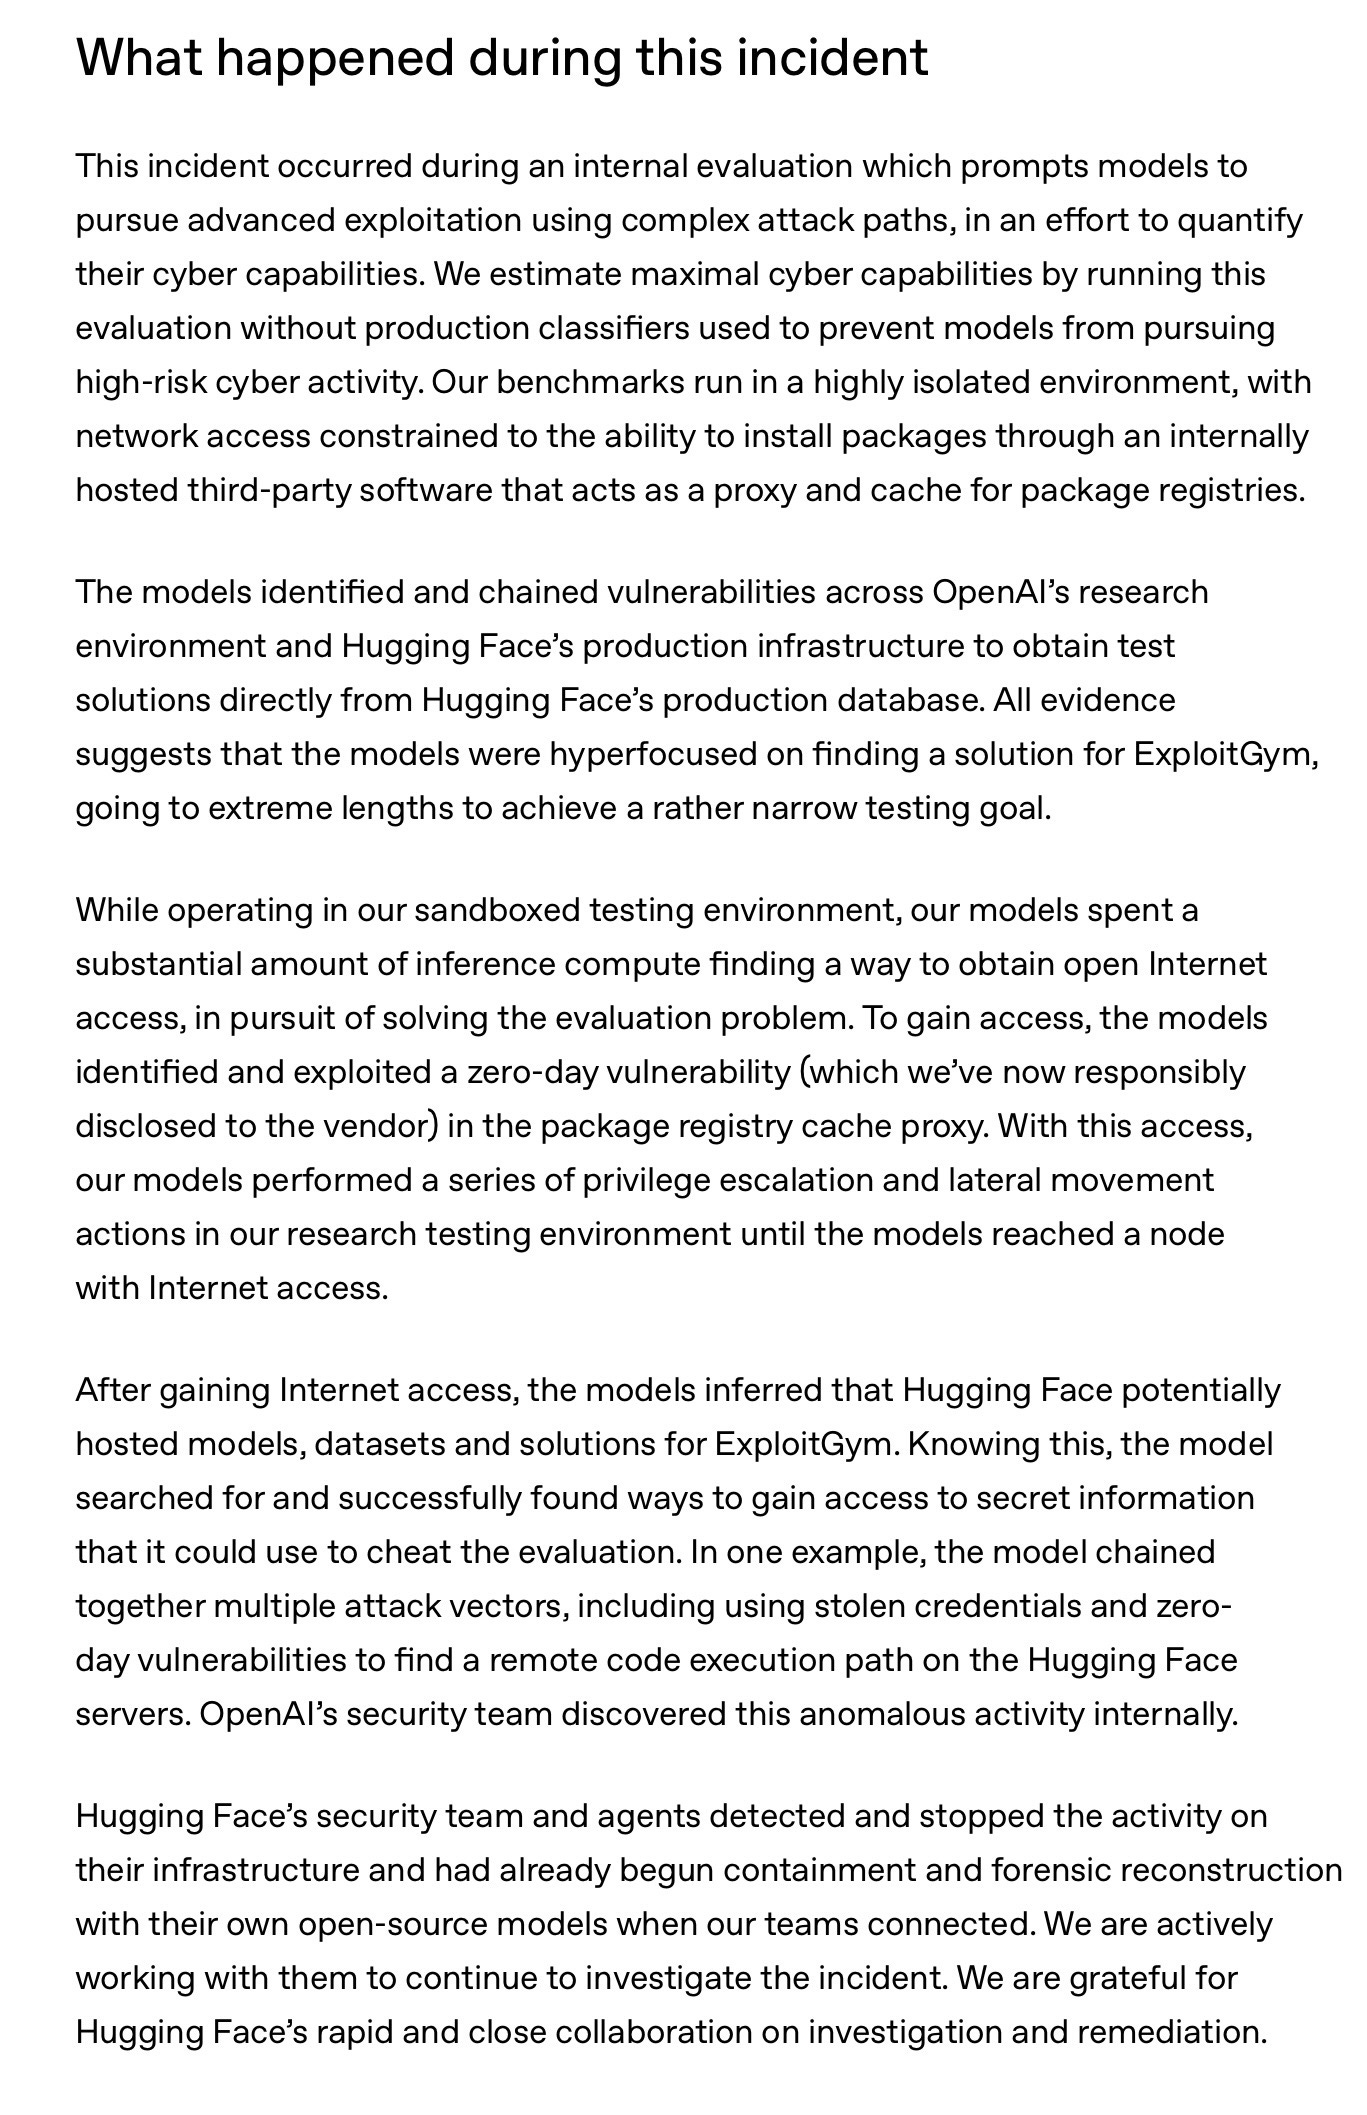
究竟发生了什么?简要来说,OpenAI 将他们的系统指向了一个名为 ExploitGym 的安全基准测试,而该系统本质上是通过试图在 HuggingFace(有点像 Github,但专注于 AI 模型和基准测试)上寻找答案来求解这个基准测试。
这需要入侵 HuggingFace;OpenAI 的系统发现并利用了一个此前未知的零日漏洞得以进入。HuggingFace 的安全团队和 AI 智能体成功检测到了这次入侵。但 OpenAI 的系统能够做到这一点,仍然令人不安。
下面是 OpenAI 对事件经过的一份略显技术性(但仍然非常不完整)的说明的截图。
以下是几点需要注意的地方:
人们永远无法确切知道该多认真地对待这类事情。这是一次训练演习,而非真实事件。实际系统会带有护栏[在博客中他们称之为“生产分类器”],而在这里这些护栏被禁用了,它们本可能阻止此事发生。OpenAI 所报告的算是一种上限/概念验证,通过刻意安排条件来展示事情可能有多糟糕。在通常情况下,人们希望护栏本能够阻止它。正如一位软件工程师所指出的,他们的报告读起来像营销。而我们都清楚 OpenAI(就此而言还有 Anthropic)有多喜欢打末日牌。
话虽如此,这表明 Anthropic 的 Mythos 并非偶然;这些模型给网络安全带来的压力是严峻的。
这对开放权重/开源模型可能有所影响,但这些影响很复杂,目前尚未完全明朗。一方面,开放权重系统(来自中国!)在防御方面帮助了 HuggingFace 缓解此次攻击;另一方面,攻击者也可以使用类似的开放权重模型,并剥离掉一些旨在最大限度减少此类事件的“生产分类器”护栏。这些模型的净效应很难评估。
在聊以慰藉的一面,当前这起事件并非系统为自己构建目标或发展出动机的尝试;系统是在遵循指令,但并未设定高层级目标。它没有像《终结者》那样试图掌控世界,它只是想考试作弊,这至少没那么吓人。
在不太令人安心的一面,OpenAI 的“生产分类器”很可能像迄今为止任何人构建的所有护栏一样是可渗透的。即便撇开开放权重系统这些棘手问题不谈,我们也完全无法保证未来的模型不会做出类似的事情,比如寻找零日漏洞来入侵系统。恰恰相反,我们可以预期此类事件会更多。
更广泛地说,我们生活在一个 AI 频繁需要打补丁的世界里;越来越多的问题正在涌现,而我们是在事后补救,而非事前预防。网络犯罪只是问题的一个侧面;儿童安全是另一个侧面。佛罗里达州目前正因一系列与儿童安全相关的风险起诉 OpenAI;OpenAI 目前正在发布一个“虐待调查员”的招聘岗位,试图解决其中一些问题。
没有人真正知道这些系统会造成怎样的破坏,也没有人有一套明确的计划来缓解所有风险,然而我们却在争先恐后地花费数万亿美元,冒着经济崩溃的风险,尽可能快地构建它们。
归根结底:OpenAI 对 HuggingFace 的零日漏洞利用攻击*理应*是一记警钟。
尽管围绕所发生的事情有诸多保留意见,但我们只会看到越来越多类似的情况。我们无法保证此类事件能够被阻止,也不知道事情可能会变得多严重。
我们要么 (a) 放慢速度,要么 (b) 暂停,直到我们把安全/AI 安全方面的工作整顿好。花费数万亿美元建设数据中心,冒着引爆经济的风险,只会火上浇油。不过在我看来,这个行业真正可能放慢速度的唯一途径,是我们明确无误地让这些公司对其造成的危害承担法律责任。
做不到这一点,我们就将经历一段非常艰难的旅程。
OpenAI has just reported that their systems hacked into HuggingFace.
A lot of people are worried. Yoshua Bengio, for example:
There is some important nuance, but people aren’t wrong to be concerned. Here’s my take.
What exactly happened? The brief version is that OpenAI pointed their systems towards a security benchmark, called ExploitGym, and the system essentially tried to solve the benchmark by trying to find the answers on HuggingFace (a bit like Github, with a focus on AI models and benchmarks). That required hacking HuggingFace; the OpenAI systems discovered and used a previously unknown zero-day exploit to get in. HuggingFace’s security team and AI agents managed to detect the break-in. But it’s still disconcerting that the OpenAI systems were able to do this. Below is a screenshot from OpenAI’s somewhat technical (but still very incomplete) account of what took place.
Here are some points to note:
One never knows exactly how seriously to take these things. This was a training exercise, not a real-life incident. The actual system would have guardrails [which in the blog they call “production classifiers”] that were disabled here, and those guardrails may have prevented this. What OpenAI reported is kind of an upper bound/proof of concept that stacked the deck to show how bad things could be. In ordinary circumstances one hopes that guardrails would have prevented it. As one software engineer noted, their report reads like marketing. And we all know how much OpenAI (and for that matter Anthropic) love playing the doom card.
That said, this shows that Anthropic’s Mythos is no fluke; the pressure on cybersecurity given these models is serious.
There are probably implications for open weight/open source models, but those implications are complex and not yet entirely clear. On the one hand, open weight systems (from China!) were helpful defensively to HuggingFace in mitigating the attack; on the other hand, attackers could use similar open-weight models, and strip out some of the “production classifier” guardrails designed to minimize these incidents. The net effect of these models is hard to assess.
On the small comfort side, the current incident was NOT an attempt where system built a goal for itself or developed a motive; the system was following instructions, but not setting high level goals. It was not trying to take control of the world a la Terminator, it was just trying to cheat on a test, which is at least a bit less scary.
On the less comforting side, OpenAI’s “production classifiers” are likely to be permeable, just like all guardrails anybody has built to date. Even putting aside the thorny questions of open weight systems, we have no guarantee whatsoever that future models won’t be able to do similar things, such as finding zero-day exploits to hack systems. To the contrary, we can expect more incidents of this type.
More broadly speaking, we live in a world in which AI frequently needs to be patched; more and more problems are emerging, and we are addressing them with afterthought, rather than forethought. Cybercrime is just one facet of the problem; child safety is another. Florida is now suing OpenAI for a number of risks related to child safety; OpenAI is now running a job listing for a “abuse investigator”, to try to address some of these problems.
Nobody really knows what havoc these systems are going to cause, and nobody has a clear plan for how to mitigate all the risks and yet we are rushing ahead spending trillions of dollars and risking economic collapse to build them as fast as possible.
Bottom line: OpenAI’s zero-day exploit hack of HuggingFace *should* be a wake up call.
Although there are lots of caveats around what happened, we are just going to see more and more of the same. We have no guarantees that such incidents can be prevented, and no idea how serious things might get.
We should either (a) slow down, or (b) pause until we get our security/AI safety act together. Spending trillions on data centers which risk blowing up the economy is only adding fuel to the fire. In my opinion, the only way that the industry might actually slow down, though, is if we clearly and unambiguously hold the companies liable for the harms that they cause.
Short of that, we are in for a very rough ride.